The Photographer's Eye: Teaching Multimodal Large Language Models to See, and Critique Like Photographers
Daiqing Qi, Handong Zhao, Jing Shi, Simon Jenni, Yifei Fan, Franck Dernoncourt, Scott Cohen, Sheng Li
摘要
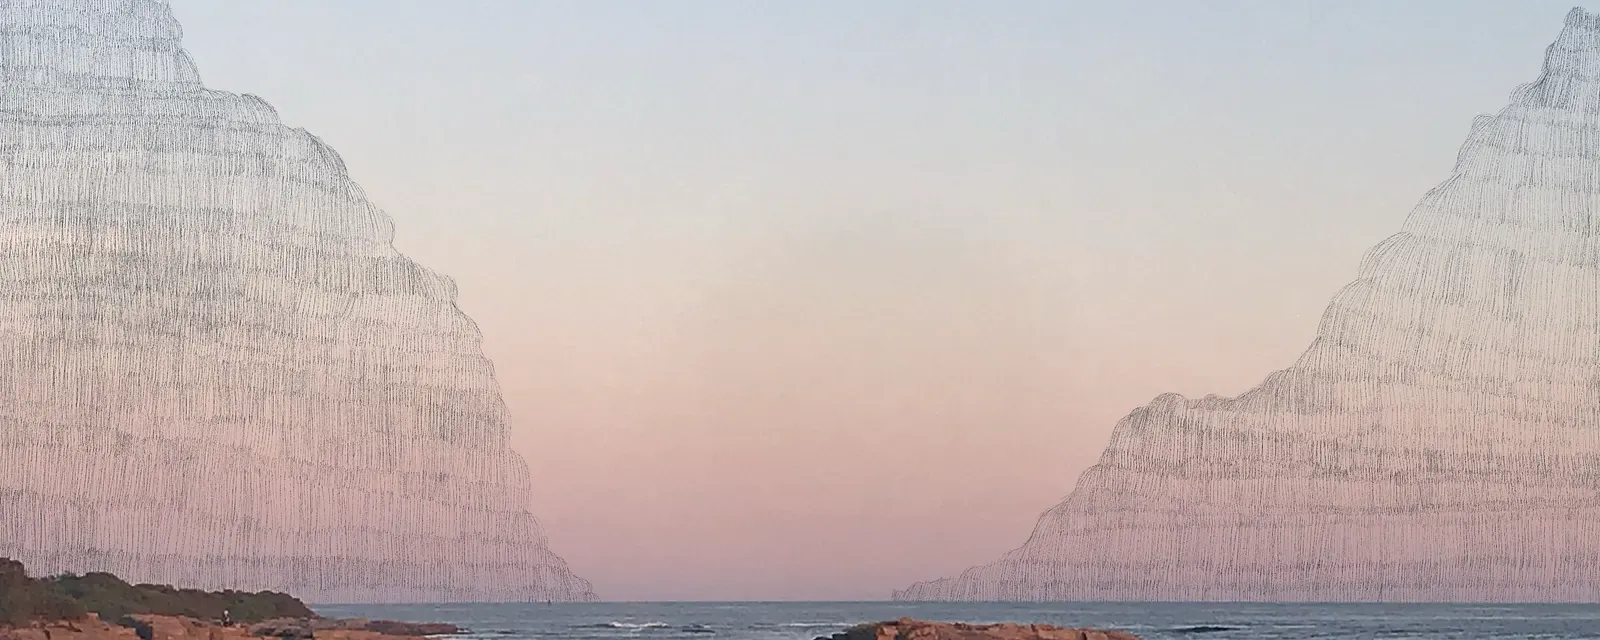
User: Are there any weaknesses in this photograph? Q-Instruct: The image features a beautiful sunset over a lush green hillside, with the sun's rays shining through the trees. The scene captures the vibrant colors of the sunset, creating a serene and picturesque atmosphere. The hillside is covered in lush green trees, providing a sense of tranquility and natural beauty. The combination of the sunset and the verdant landscape creates a captivating and visually stunning scene. AesExpert: This image looks very clear. The colors in this image are rich and vibrant, with a good color combination, making the picture appear more vivid and bright. The lighting in this image is strong, creating a warm and soft atmosphere, with a strong contrast between light and dark. The composition of this image is a high horizon composition, highlighting the texture in the lower half of the picture. Therefore, this image looks quite beautiful. PhotoEye: The composition of this image could be improved by straightening the horizon to create a more balanced and visually appealing frame. Additionally, the presence of lens flare may be distracting and detract from the overall impact of the image. To address this, the photographer could consider using a lens hood or adjusting their shooting angle to minimize the effect of the flare. Furthermore, the tilted horizon could be corrected to create a more stable and visually appealing composition. Finally, the lighting could be more nuanced, with a more subtle transition between highlights and shadows to create a more natural and inviting atmosphere.
问问这篇 Paper
智能体会读完全文。
Lune 把这篇 Paper 索引到了每一个公式,引用它的顶会 Paper 也一样。你提问,回答直接引用原文。
引用它的顶会 Paper4
- Improve Temporal Reasoning in Multimodal Large Language Models via Video Contrastive DecodingDaiqing Qi, Dongliang Guo, Hanzhang Yuan, Handong Zhao 等NeurIPS 2025 · 被引用 5 次
- Venus: Benchmarking and Empowering Multimodal Large Language Models for Aesthetic Guidance and CroppingTianxiang Du, Hulingxiao He, Yuxin PengCVPR 2026 · 被引用 3 次
- A³: Towards Advertising Aesthetic AssessmentKaiyuan Ji, Yixuan Gao, Lu Sun, Yushuo Zheng 等CVPR 2026
- How to Take a Memorable Picture? Empowering Users with Actionable FeedbackFrancesco Laiti, Davide Talon, Jacopo Staiano, Elisa RicciCVPR 2026
它引用的顶会 Paper17
- Learning Transferable Visual Models From Natural Language SupervisionAlec Radford, Jong Wook Kim, Chris Hallacy, Aditya Ramesh 等ICML 2021 · 被引用 47,906 次
- Visual Instruction TuningHaotian Liu, Chunyuan Li, Qingyang Wu, Yong Jae LeeNeurIPS 2023 · 被引用 11,349 次
- Flamingo: a Visual Language Model for Few-Shot LearningJean-Baptiste Alayrac, Jeff Donahue, Pauline Luc, Antoine Miech 等NeurIPS 2022 · 被引用 6,707 次
- InstructBLIP: Towards General-purpose Vision-Language Models with Instruction TuningWenliang Dai, Junnan Li, Dongxu Li, Anthony Meng Huat Tiong 等NeurIPS 2023 · 被引用 4,013 次
- MiniGPT-4: Enhancing Vision-Language Understanding with Advanced Large Language ModelsDeyao Zhu, Jun Chen, Xiaoqian Shen, Xiang Li 等ICLR 2024 · 被引用 3,079 次
相关 Paper
- Improving Lens Flare Removal with General-Purpose Pipeline and Multiple Light Sources RecoveryYuyan Zhou, Dong Liang, Songcan Chen, Sheng-Jun Huang 等ICCV 2023 · 被引用 35 次
- SLCFormer: Spectral-Local Context Transformer with Physics-Grounded Flare Synthesis for Nighttime Flare RemovalXiyu Zhu, Wei Wang, Xin Yuan, Xiao WangAAAI 2026
- How to Train Neural Networks for Flare RemovalYicheng Wu, Qiurui He, Tianfan Xue, Rahul Garg 等ICCV 2021 · 被引用 97 次
- A fitted radiance and attenuation model for realistic atmospheresAlexander Wilkie, Petr Vévoda, Thomas Bashford-Rogers, Lukas Hosek 等SIGGRAPH 2021 · 被引用 20 次
- Understanding and Tackling Scattering and Reflective Flare for Mobile Camera SystemsFengbo Lan, Chang Wen ChenACM MM 2024 · 被引用 4 次